BackContext is live: one context layer for every agent you run.
Explore BackContext

Your own AI model, trained on how your company works

We fine-tune open-weight models on your real work, connect them through BackContext, and keep them improving. Frontier-level accuracy on your tasks, at a fraction of the cost.

Built on the best open-weight models
Icon
Services

Everything it takes to own your AI

IconIcon
All services
All services
IconIcon
665K+

Work records captured

97.4%

Average task accuracy

46×

Lower cost per task

Frontier models are brilliant generalists. Your business runs on a few hundred specific tasks, done the same way thousands of times a day.

We train a model that does exactly those tasks, better and for less, and keep it improving.

IconIcon
Learn more
Learn more
IconIcon
Image
Icon
How it works

One loop that keeps getting smarter

Icon
01. Record & connect

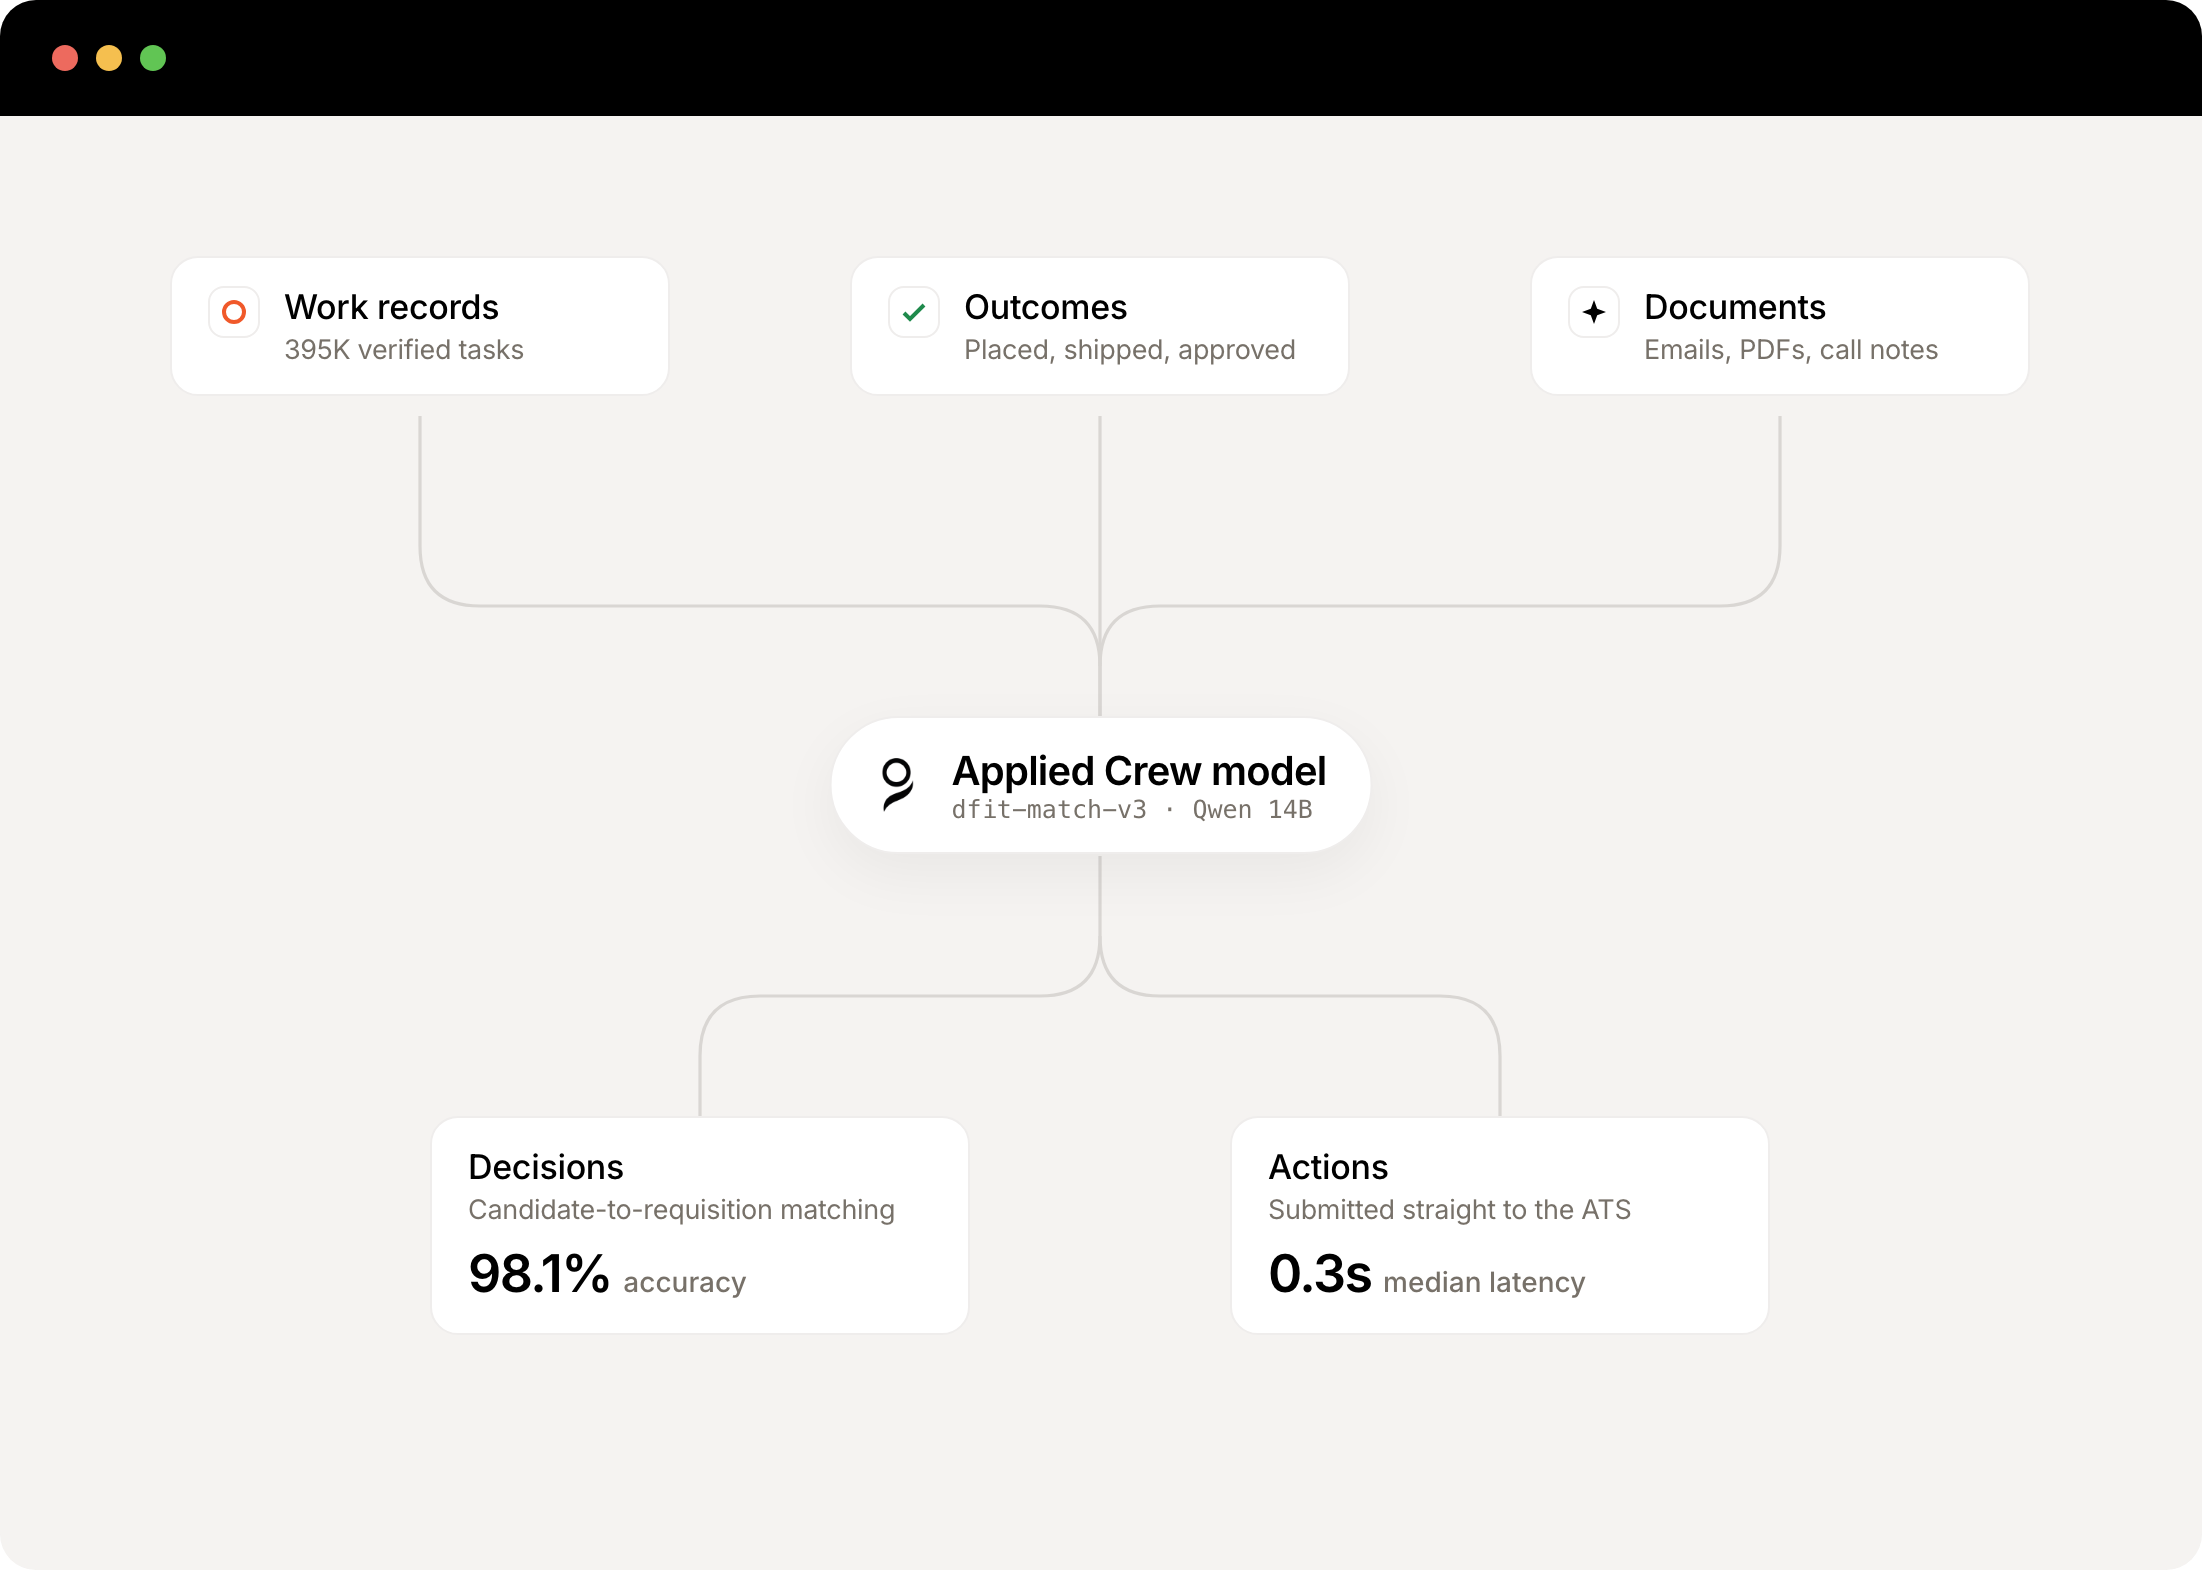
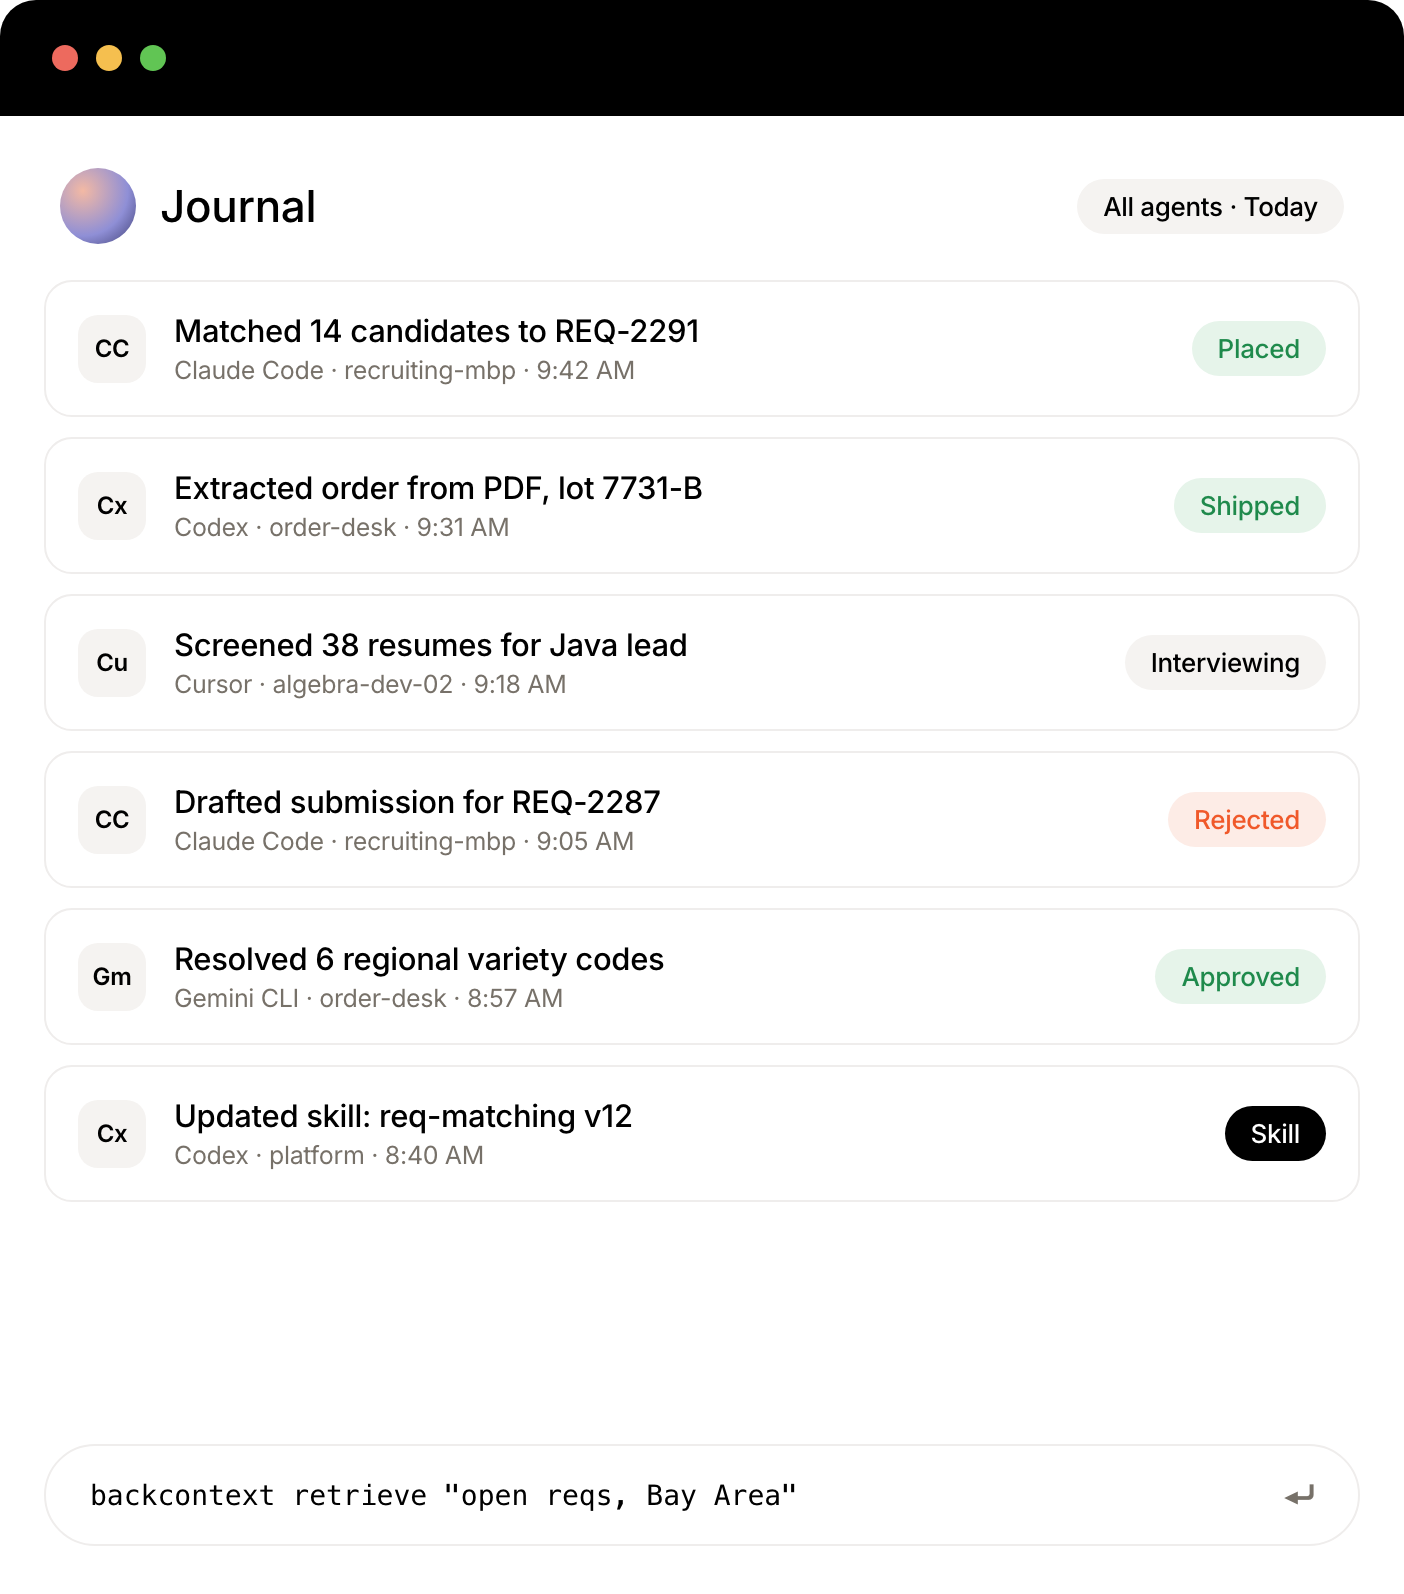
BackContext records every task your team and agents complete, and links it to what actually happened

Icon
02. Verify & train

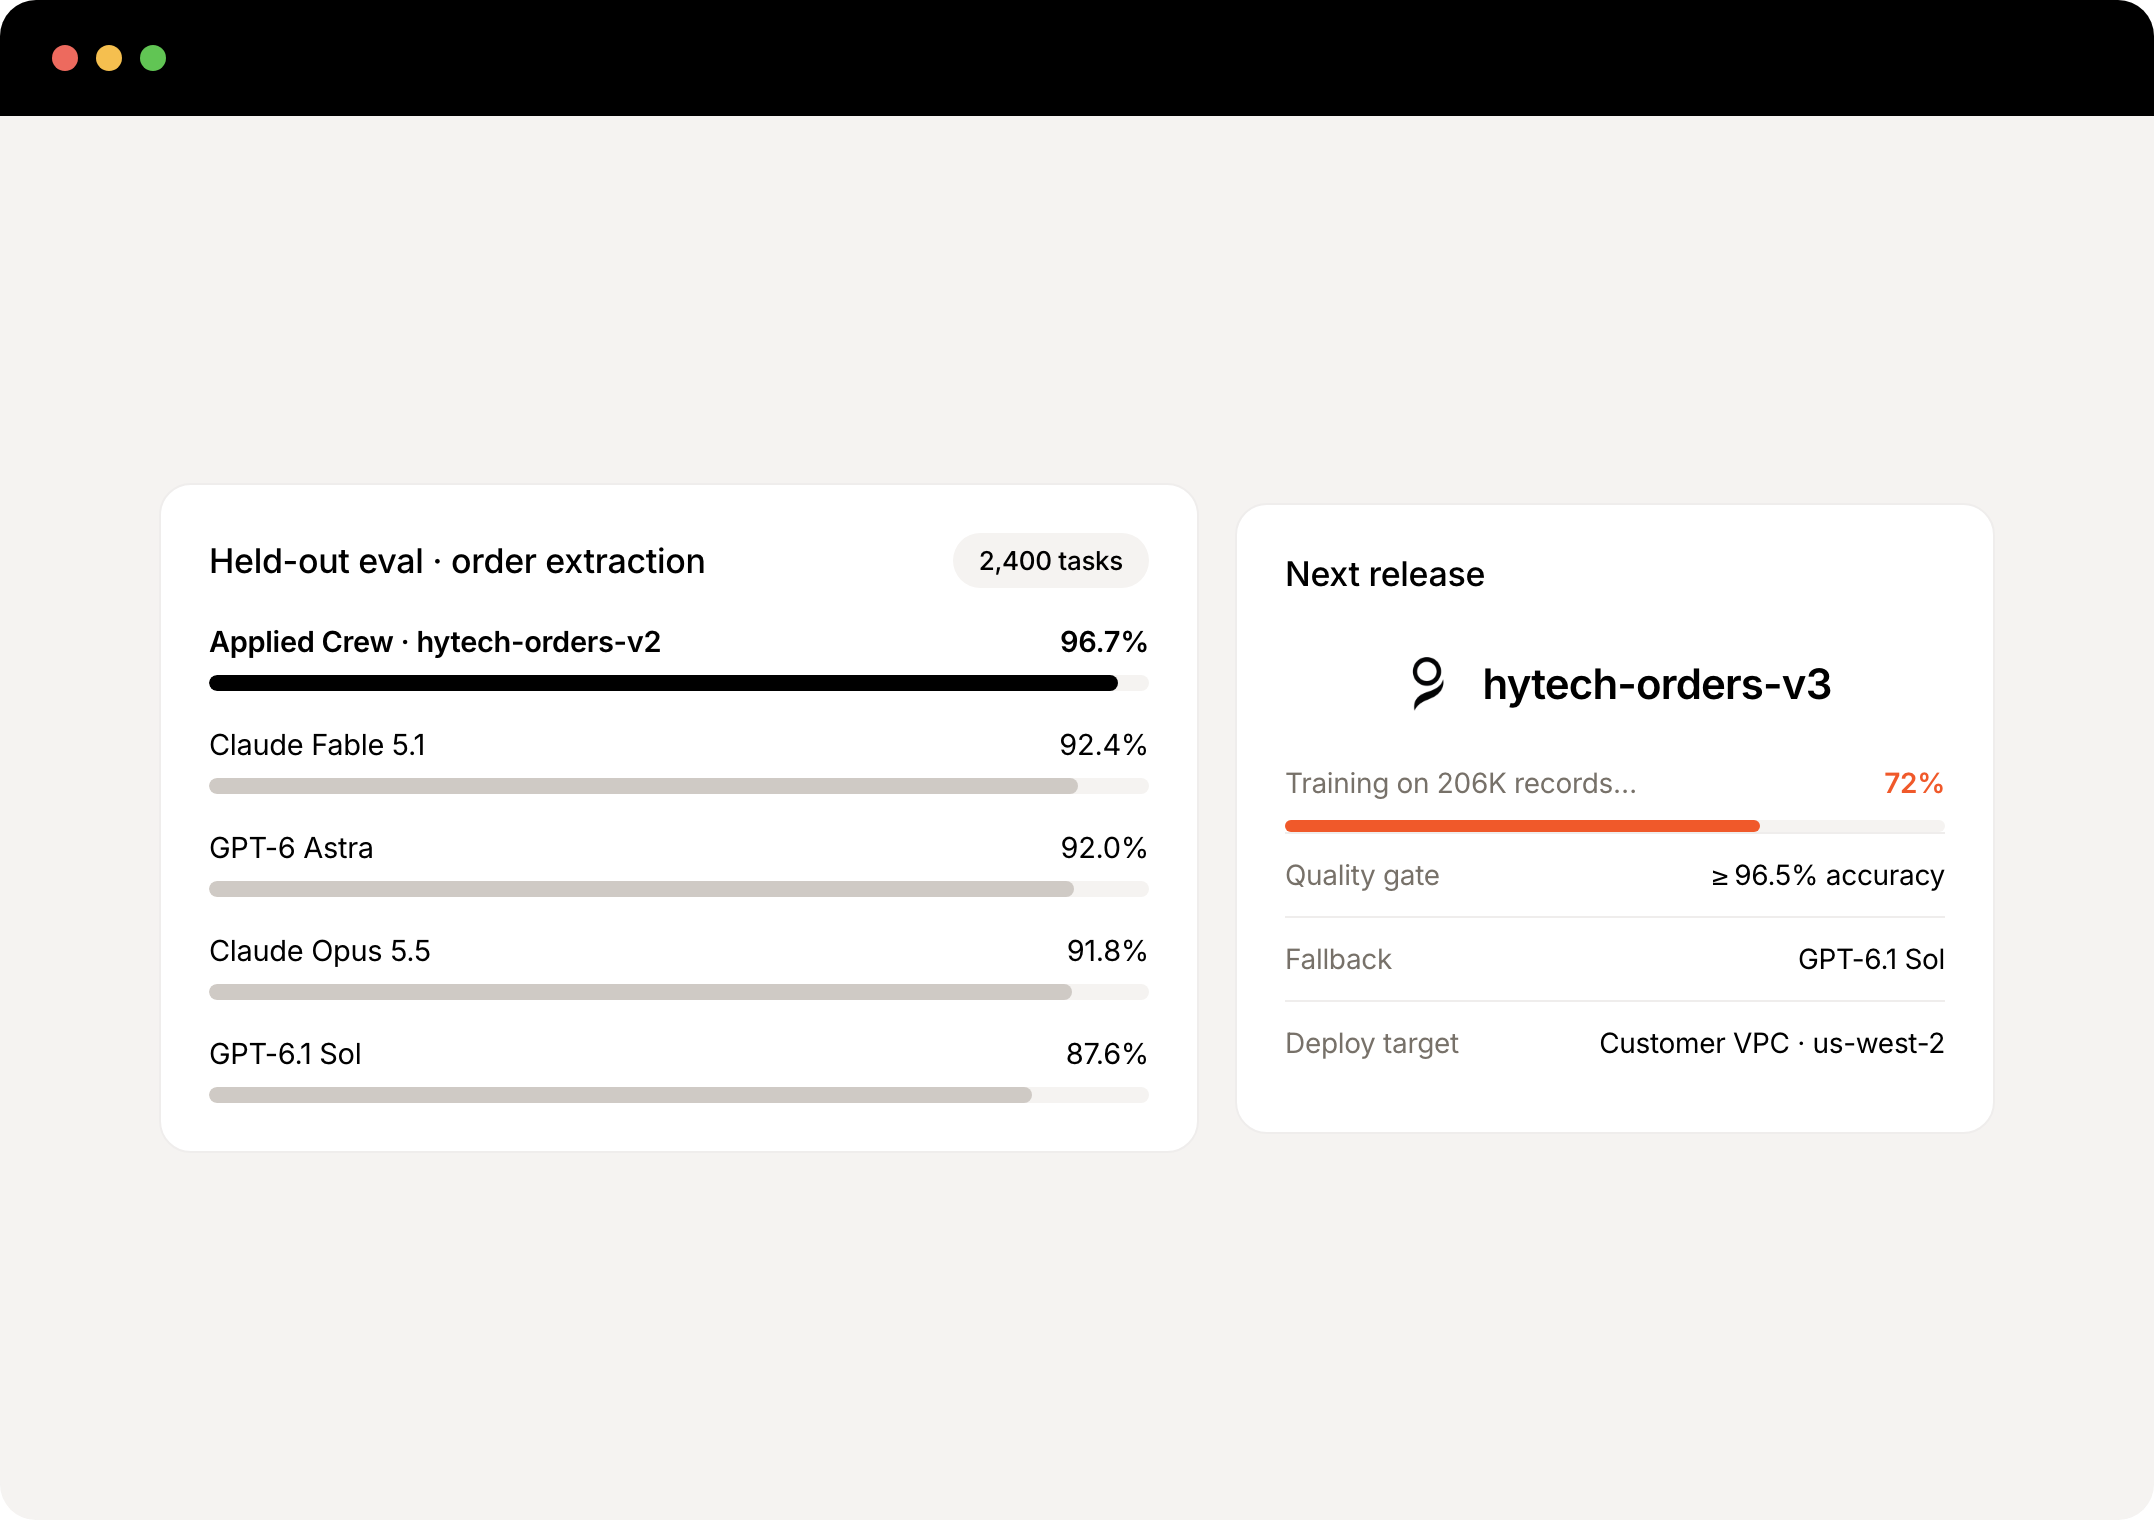
Verified outcomes become training data. We fine-tune an open model and benchmark it against Opus 5.5, Fable 5.1 and GPT-6 Astra

Icon
03. Deploy & improve

It ships behind a quality gate with frontier fallback. Every new outcome makes the next version better

Icon
Case studies

Real work, measured in production

IconIcon
All case studies
All case studies
IconIcon

Every engagement starts with one question: can a model trained on your work beat the best frontier model at your task, for less?

Icon
Benefits

Why teams switch to Applied Crew models

Frontier accuracy on your tasks

97.4% on held-out evals, ahead of Fable 5.1 and GPT-6 Astra
Image
46× lower cost per task

$1.40 per 1,000 tasks, against $65 on GPT-6 Astra
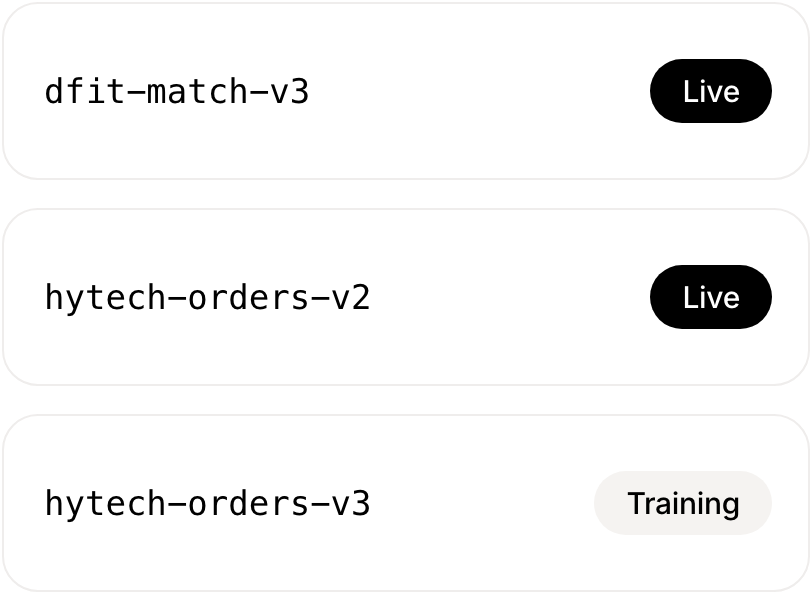
Applied Crew models running in production
Your weights, your cloud

Deploy in your own VPC. No per-token bill, no lock-in

Image
Works with every agent you run

Claude Code, Codex, Cursor and any MCP client, through BackContext
Image
Better every week

Every verified outcome becomes training data for the next version
Image
Icon
Customer reviews

Trusted by the teams who run the work

Icon
“We stopped paying frontier prices for a task our own model now does better. The eval report made the decision easy.”
Image
VP, Recruiting Operations

Staffing

Icon
“BackContext was running across every agent tool in a day. Five weeks later we had the training data most teams spend a year collecting.”
Image
Head of Delivery

IT services

Icon
“Our order desk used to retype every email. Now the model reads them the way our team does, including the abbreviations nobody documented.”
Image
Director of Operations

Agriculture

Icon
“They benchmarked against Opus 5.5 and GPT-6 Astra on our own data before we committed to anything. That’s the only comparison that matters.”
Image
CTO

Logistics

Icon
“The model runs in our VPC. Legal signed off in a week instead of a quarter.”
Image
General Counsel

Healthcare services

Icon
“Every week the model gets a little better, because every outcome goes back into training. That compounding is the product.”
Image
COO

Insurance

Icon
Blog

Research and field notes

IconIcon
All posts
All posts
IconIcon
Icon
FAQ

Frequently asked questions

Have more questions?

IconIcon
Contact us
Contact us
IconIcon

Is a fine-tuned open model really as good as Opus 5.5 or GPT-6 Astra?

How much data do we need?

Where does the model run?

What happens to our data?

How long until our first model is in production?